Pooled Pattern
Analytical: Centralised
Data Movement: Row level data
The defining feature of the Pooled Pattern is that row-level data leaves a TRE, whether persistently or temporarily, and whether or not it has been anonymised or pseudonymised. Outside of TREs this is the most common method, where researchers would be accustomed to having the data in one place where they can perform any analysis or learning.
This approach requires a very high level of trust between TREs as it requires sharing of row-level data between TREs. Disclosure control can still be applied before the data leaves the TRE network. It is however by far the most powerful for a user as the analyses and learning are almost unlimited.
Analyses
Because the analysis runs on the pooled data, every result is exact by definition and requires no approximation, as may be required in the Traditional and Shared Patterns.
Most statistics and models can be calculated without pooling, using one of the other two patterns. The Pooled Pattern is needed when an analysis depends on having individuals’ records together:
| Analysis | Why it needs pooled data |
|---|---|
| Linking records across TREs | Bringing together data held about the same individuals in different TREs, where each TRE holds different information about them |
| Removing duplicate individuals | Individuals present in more than one TRE are otherwise counted more than once |
| Different variables held for the same individuals | The Traditional and Shared Patterns assume each TRE holds the same variables for different individuals |
| Analyses with no decomposable form | For example, unstratified Cox regression, or methods that need the full dataset at once |
| Exploratory analysis and data quality checks | Where the method is not known in advance, so cannot be broken down into results each TRE calculates |
What counts as Pooled
Some approaches move row-level data without it appearing in readable form. These are still the Pooled Pattern, because data about each individual leaves the TRE:
- Privacy-preserving record linkage: sending hashed or encoded identifiers for each individual is row-level data moving. This differs from a sketch of hashed identifiers, such as the HyperLogLog sketch in the Traditional Pattern, which summarises the identifiers rather than listing them.
- Secure multi-party computation and trusted execution environments: row-level data moves, but in encrypted form, so no party sees another TRE’s records. These are Pooled, but with a lower trust requirement than pooling readable data.
Trust and egress
This pattern is most likely associated with the Full central control Egress Inspection Pattern: data that would not normally be allowed to leave a TRE moves within the federation, and the normal egress check is performed before results leave the boundary of the federation of TREs.
Variance in implementation
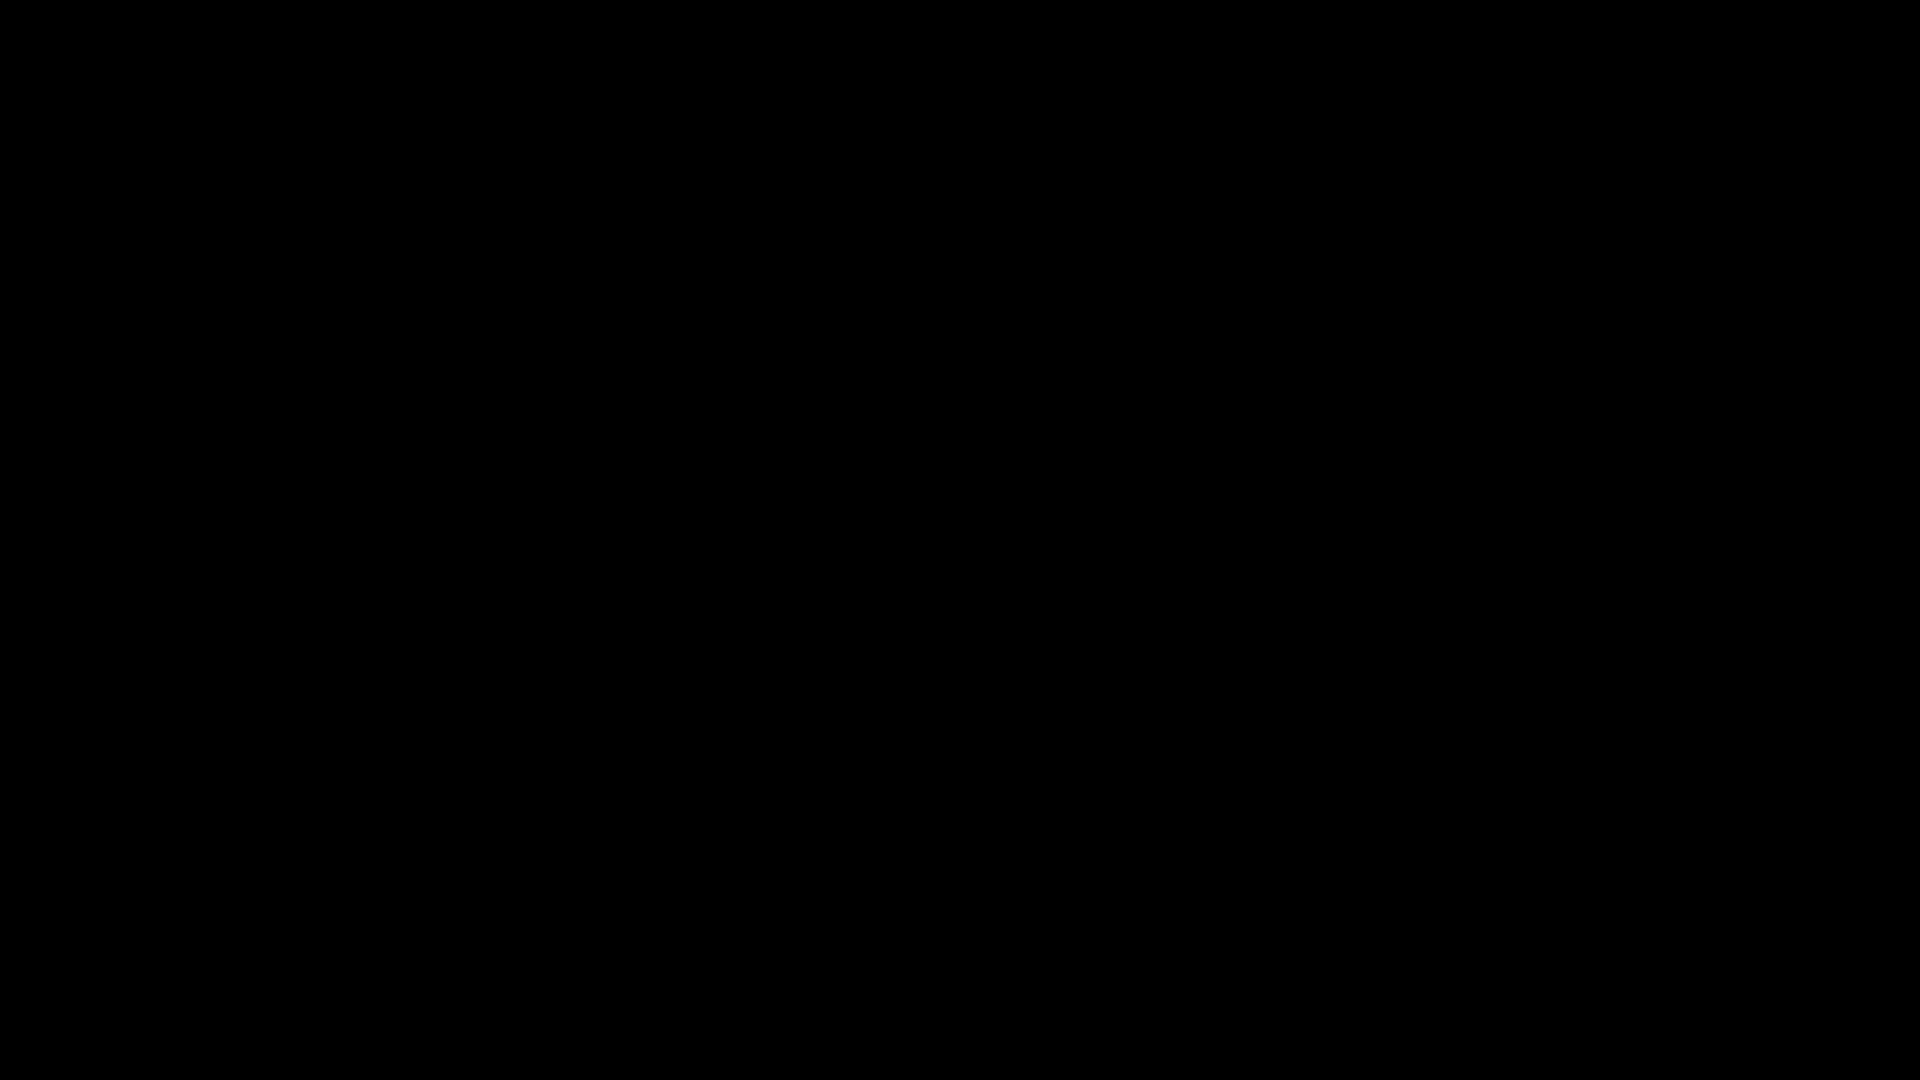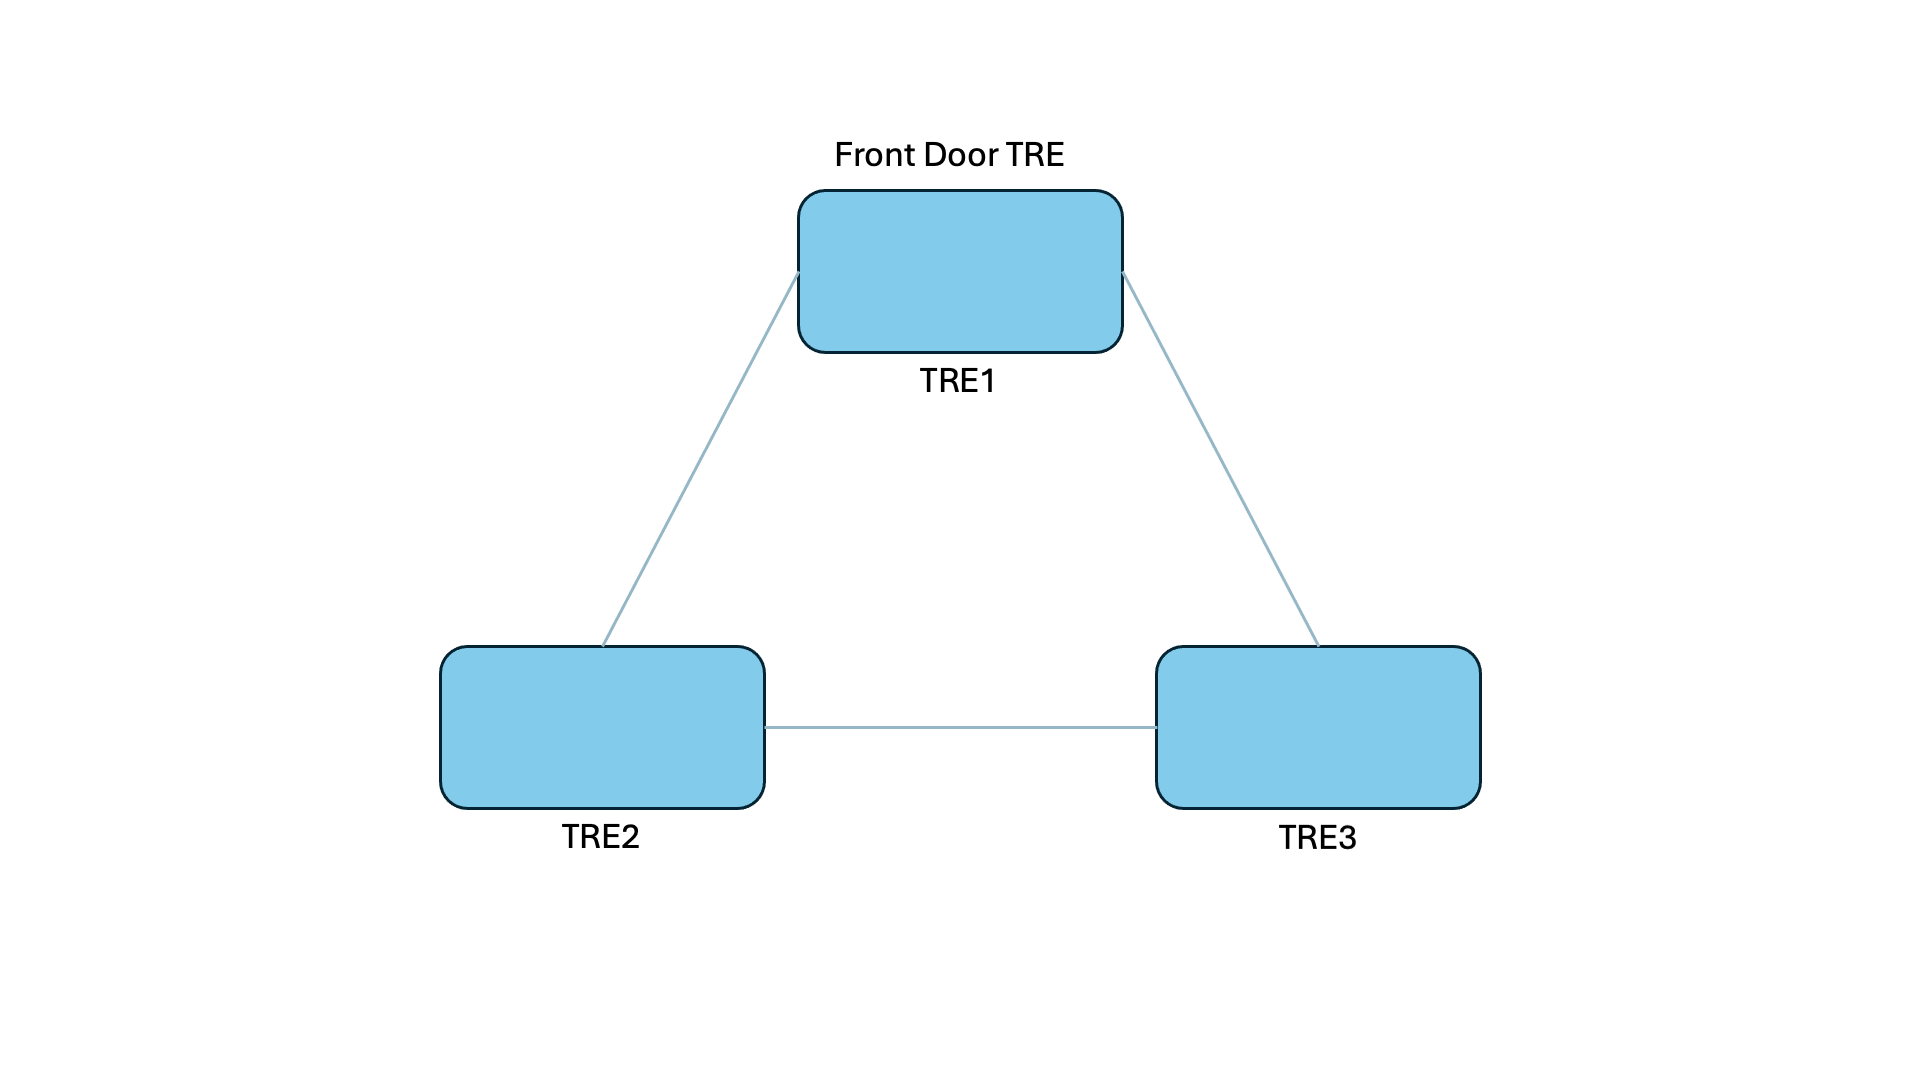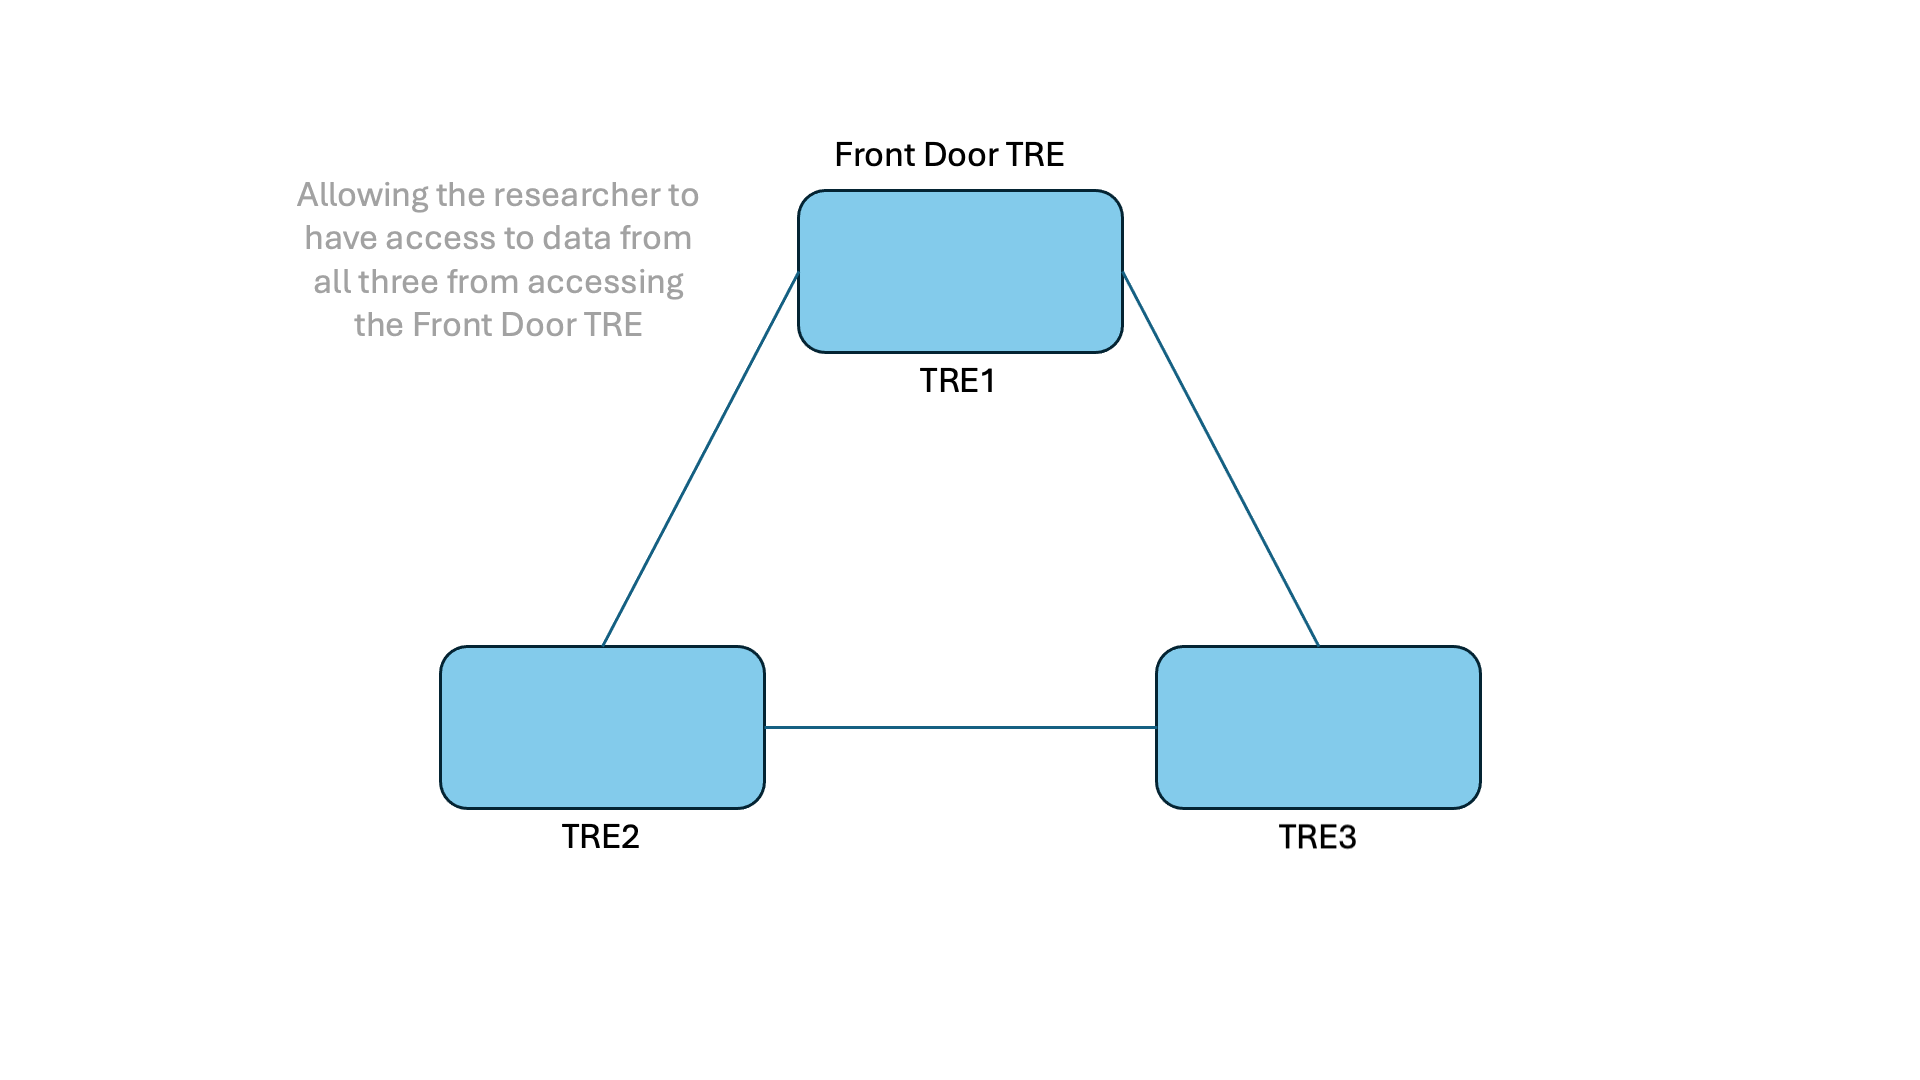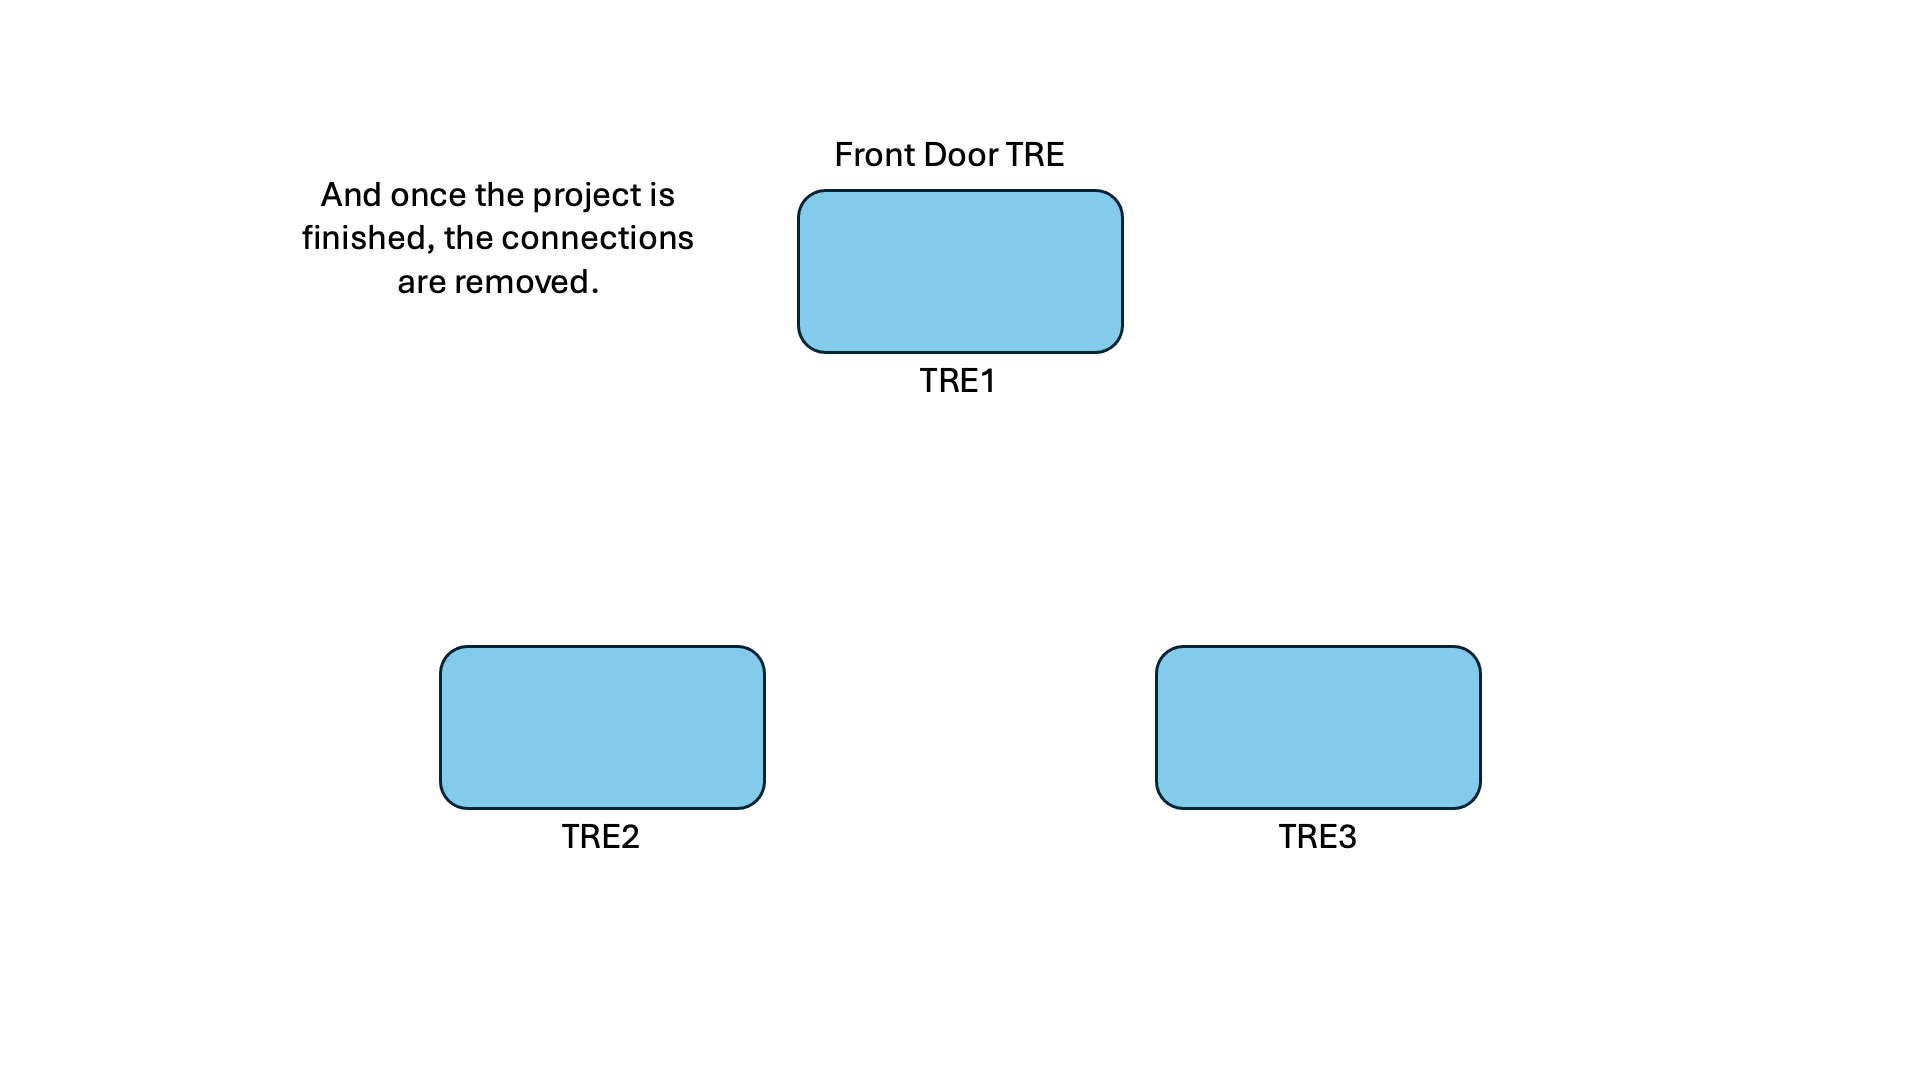
An emerging implementation of the Pooled Pattern is from the DARE UK TREvolution programme. They are exploring a project-specific network being created between the TREs, to either move or provide the researcher with a view of the data that makes it appear as if the data is all in one location.