Traditional Pattern
Analytical: Isolated
Data Movement: Summary
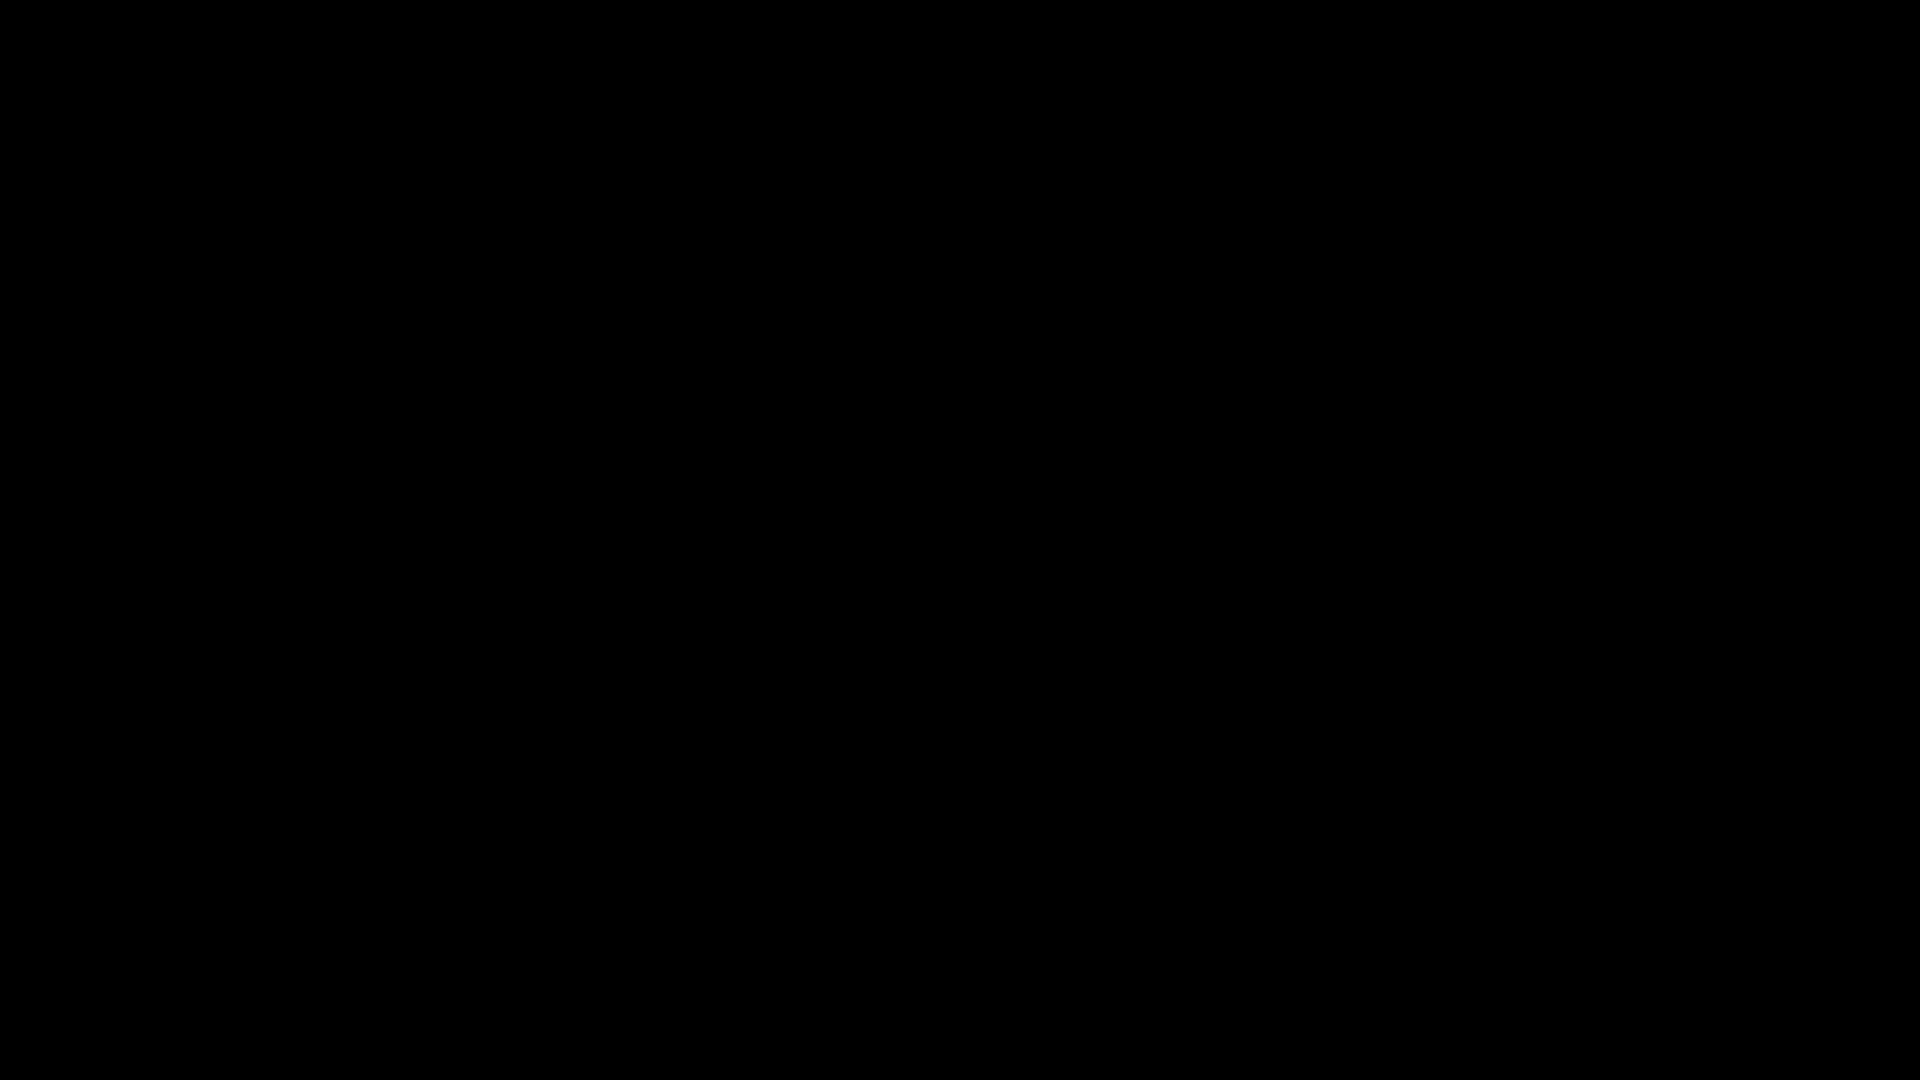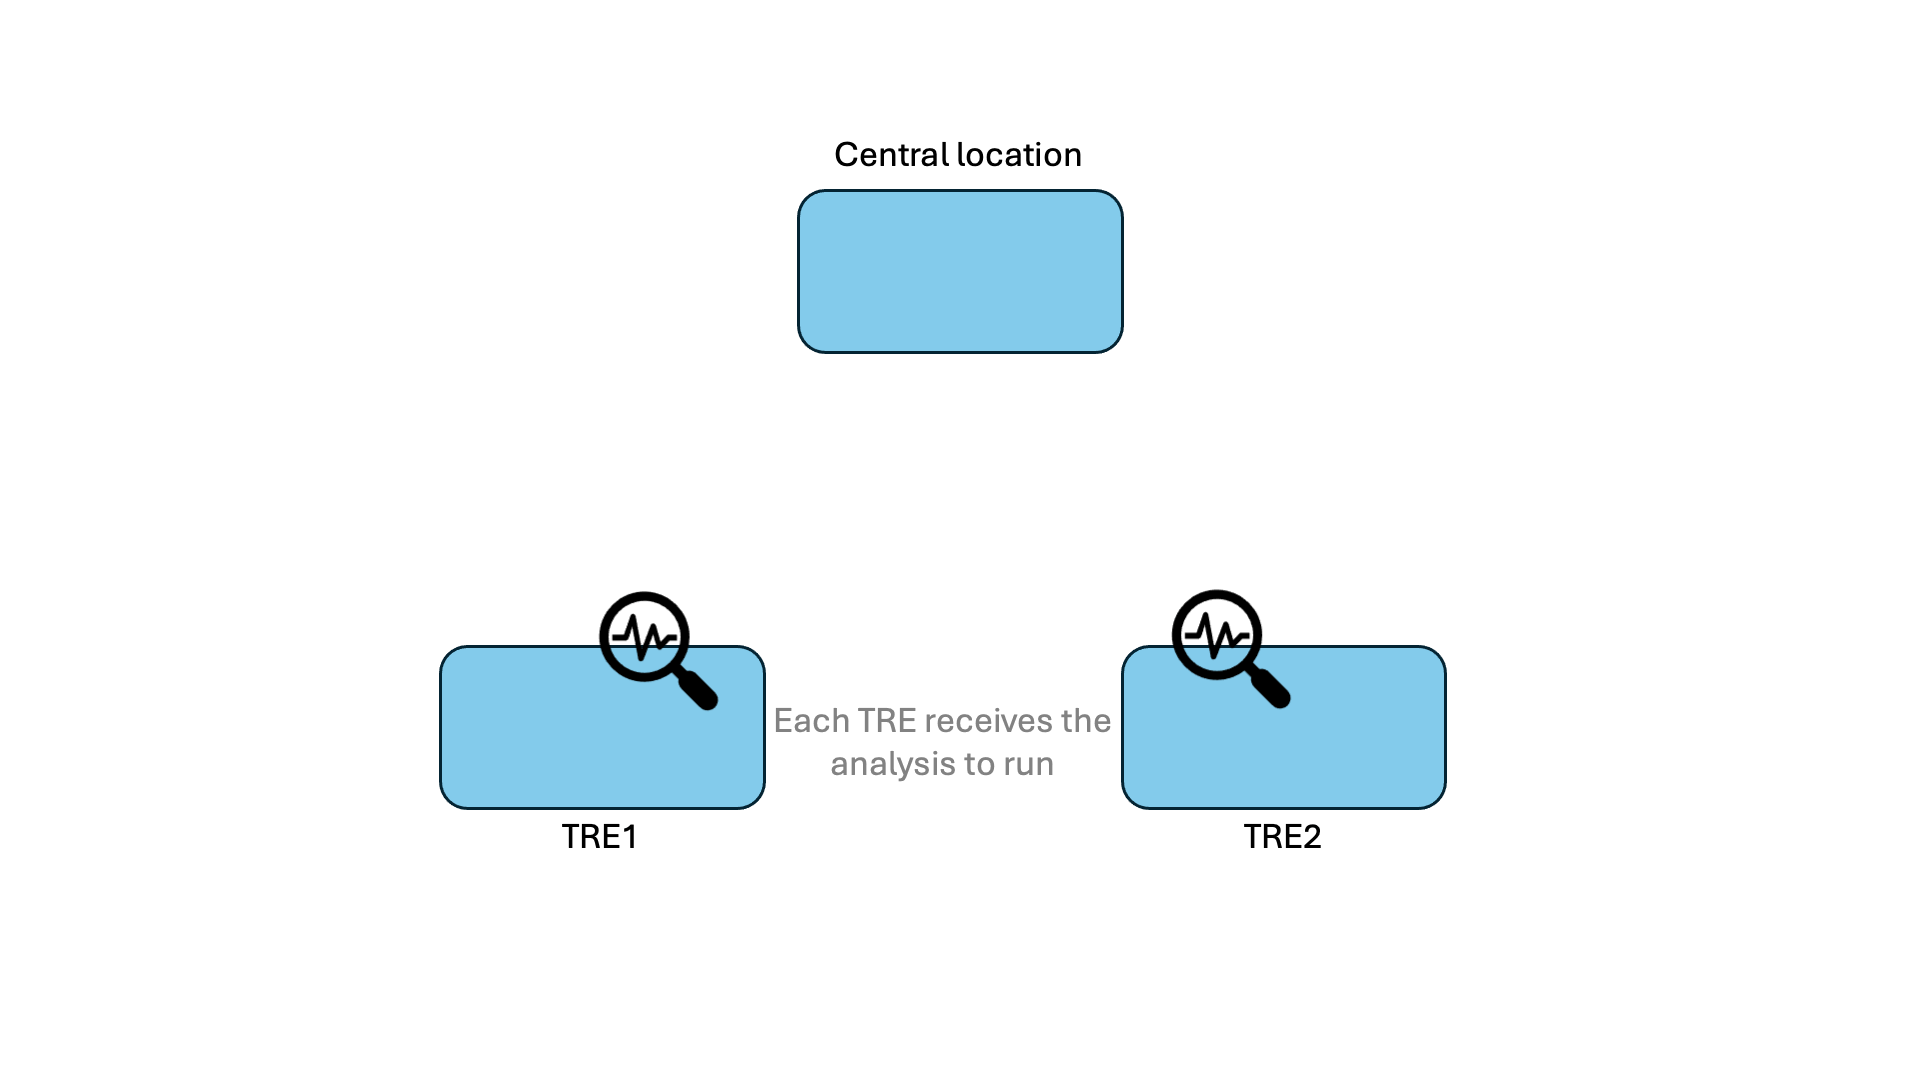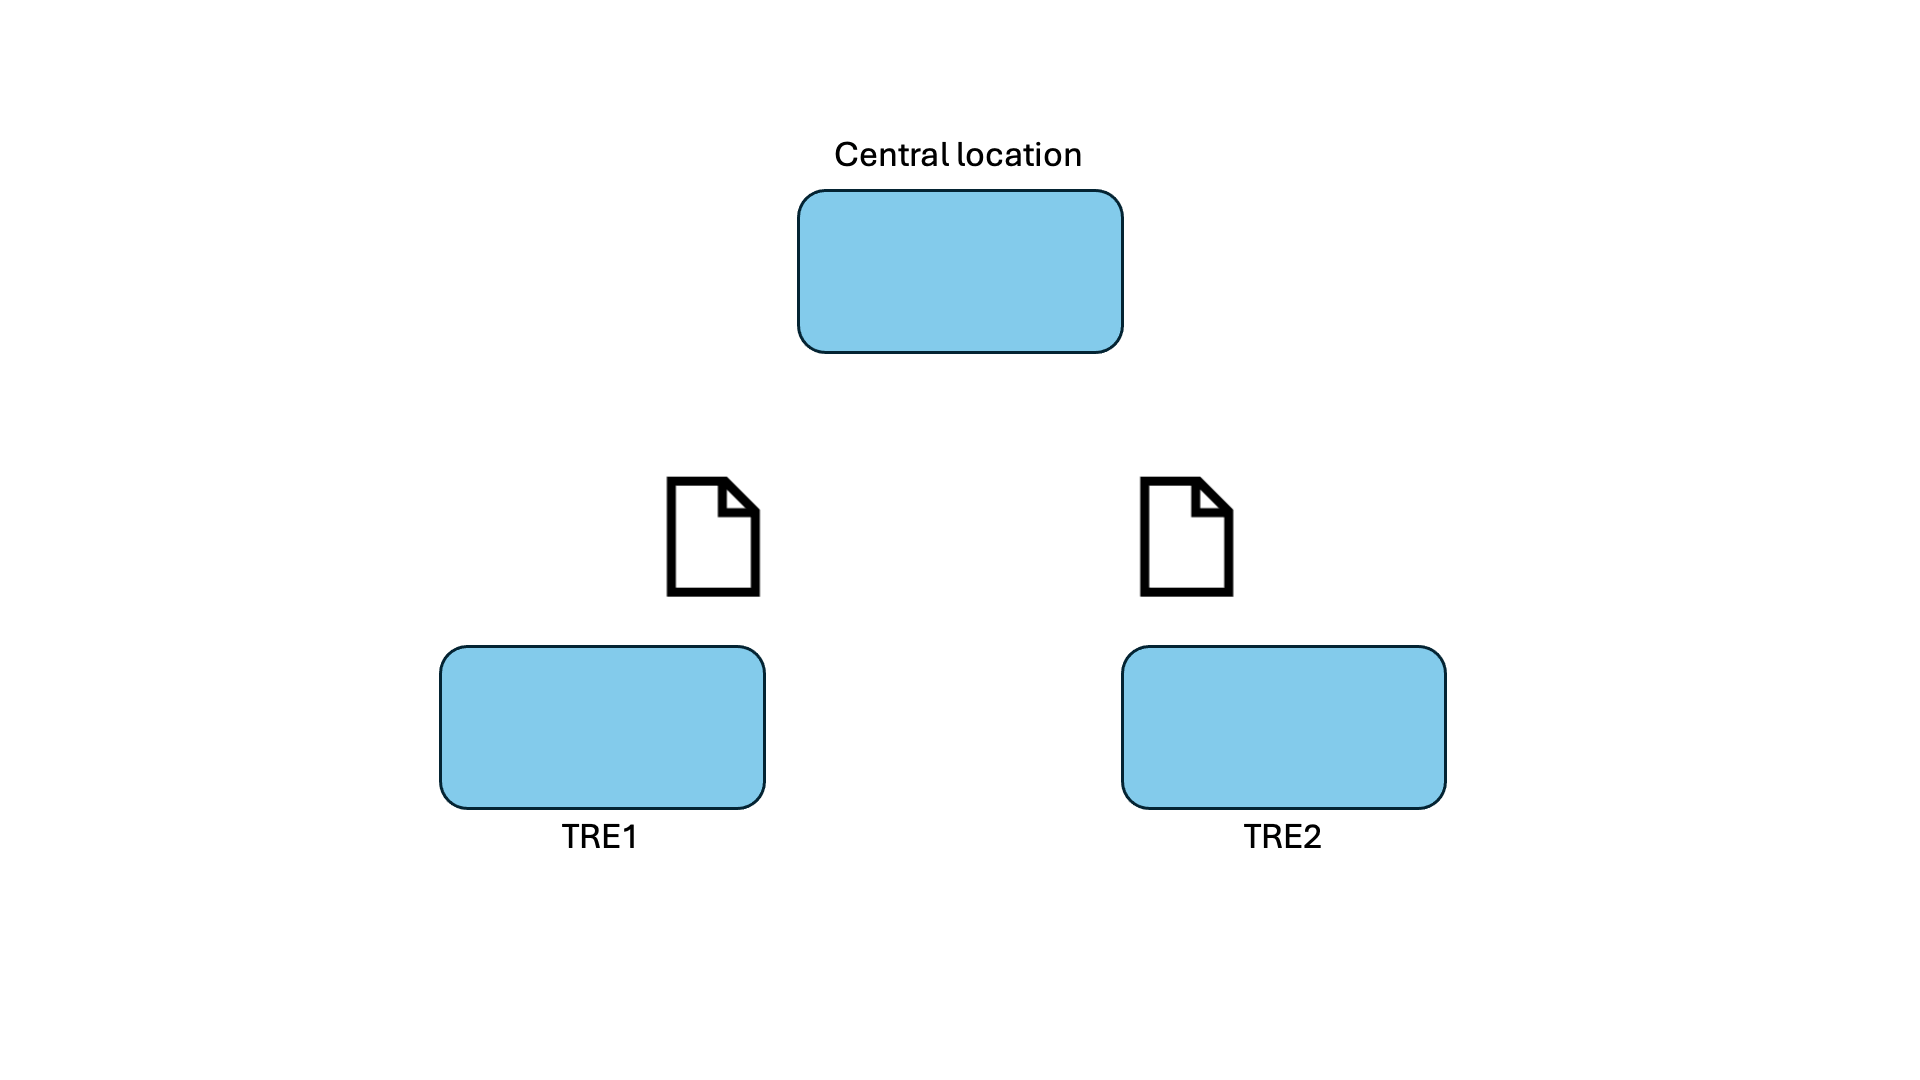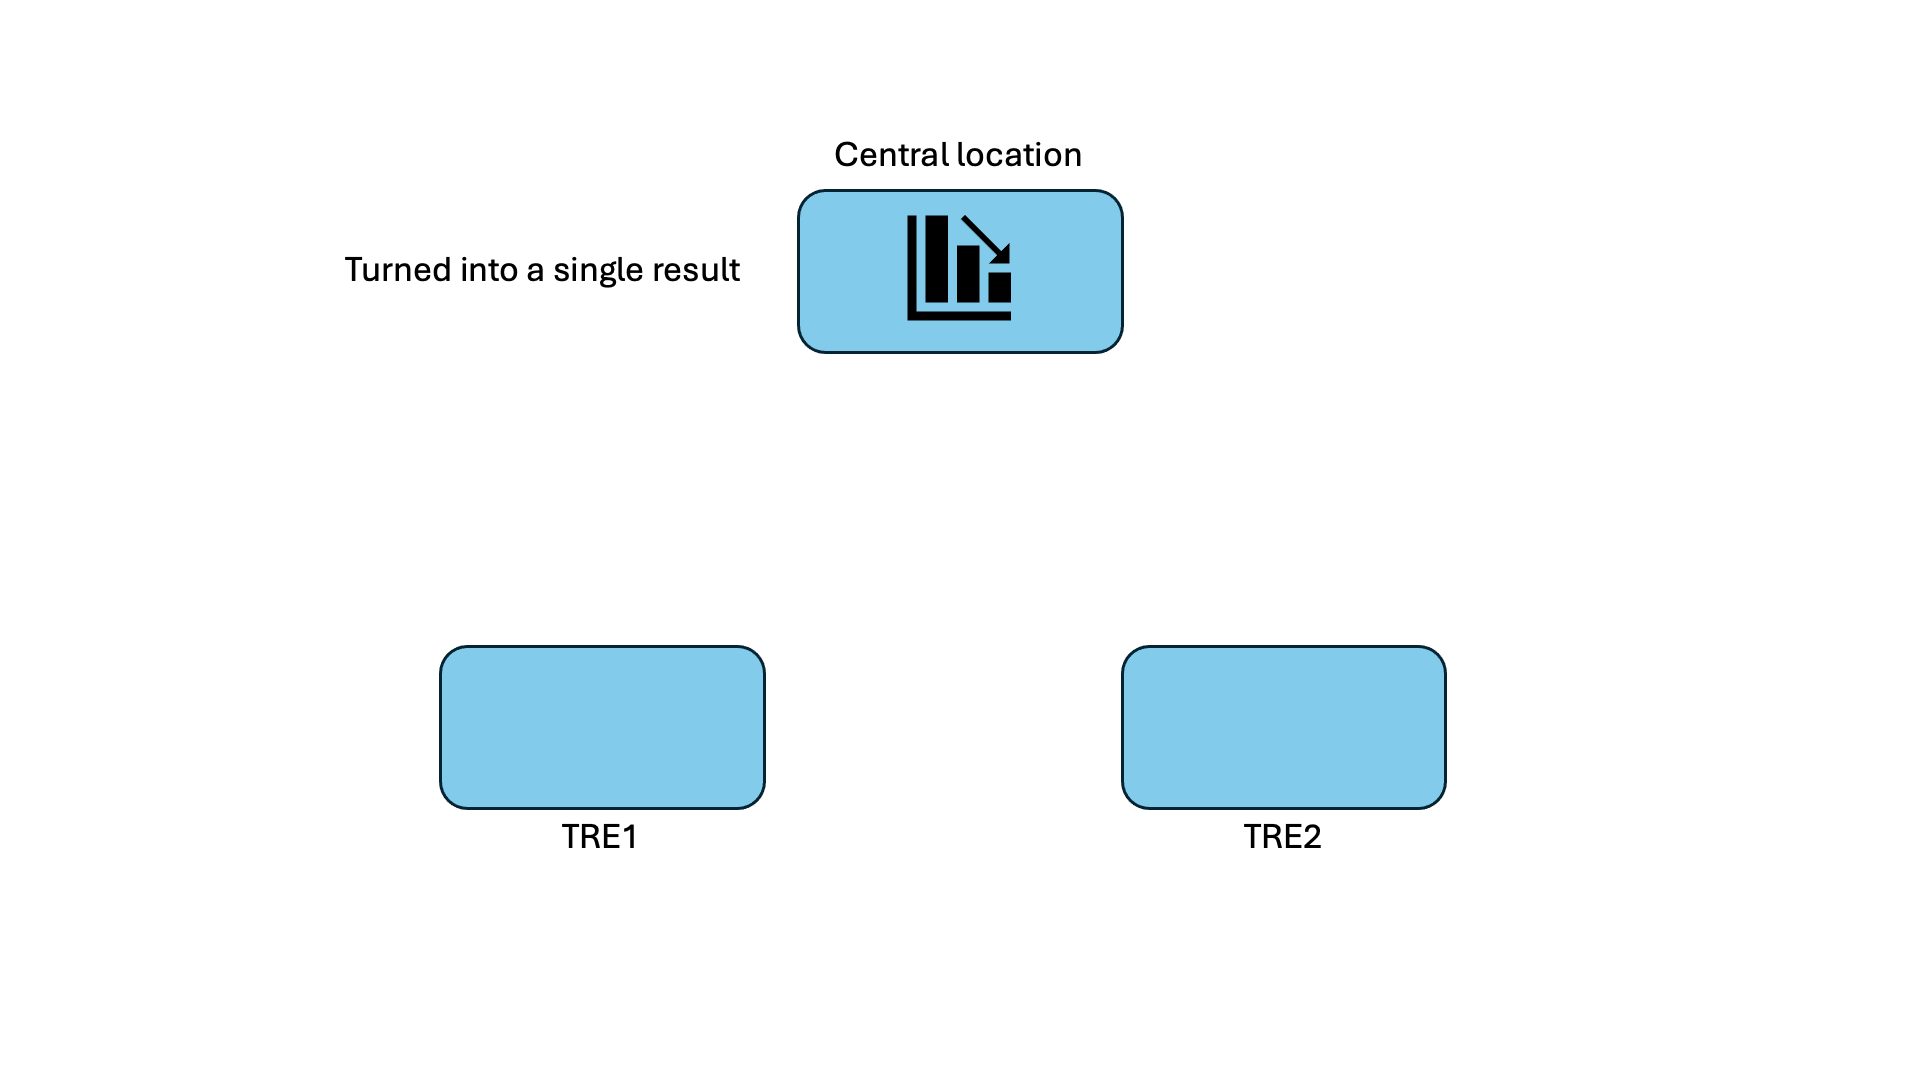
The most common method of federated analytics carries out a local computation in each location separately to generate summary results. This pattern requires the lowest trust between TREs, as each analysis is undertaken independently and no TRE receives results from another. One limitation of this approach is that data cannot be linked, as no row-level attributes are shared.
In the simplest case, a researcher carrying out this kind of analysis wants to calculate a separate result of the analysis for each location. In this case, any analysis that can be run within the boundary of the TRE, constrained only by the compute and permissions from the TRE, is possible. The results can then be compared side by side, tested for differences between locations, or combined in a meta-analysis (see Compared).
In other cases, a researcher wishes to estimate a result across locations, combining local results. For example, they could carry out a meta-analysis, calculating a summary of the data in each location so they can use statistical methods to estimate some overall result from each location’s summary. For a more limited set of results, discussed below, it is possible to use a Traditional pattern to calculate the result as if the data were in a single, pooled dataset.
The analyses that can be run within the boundary of the TRE are almost unlimited and constrained only by the compute and permissions from the TRE. Egress can be applied which will limit the results that can be analysed together.
Analyses
In the Traditional Pattern each analysis is isolated: it is carried out separately within each TRE, and the results are combined, compared or analysed centrally, based on what has been allowed out through the egress process. Some analyses can be broken into parts whose results combine to give the same answer as the pooled data. Others are run in full at each TRE, and the results are compared centrally.
In that sense the analyses whose results can be compared between TREs are almost endless and are only constrained by what the TRE is likely to allow to leave. Combining these results in a meta-analysis relies on having an applicable statistical approach.
The analyses below assume each TRE sends its results in a single pass, using settings (such as time grids, histogram bins or starting values) agreed before the analysis starts. If anything calculated from one TRE’s data is sent into another TRE, the analysis becomes Shared (see When an analysis becomes Shared).
These tables are not comprehensive, and describe common analyses that can be achieved with the traditional pattern.
Compared
Any analysis that can run within a TRE can be run in full at each TRE, with the results returned for each location. This includes models that cannot be combined exactly, such as Cox regression, logistic regression with continuous covariates, mixed models and machine learning models. Differences between locations are often a finding in their own right.
| Aim | What each TRE sends | How the results are used |
|---|---|---|
| Describe each population | Summary tables, such as counts, rates, prevalence, means and distributions | Compared side by side, for example a table of characteristics with a column per location |
| Test for differences between locations | Estimates with their standard errors, or the totals behind them (such as n, mean and variance) | Tested centrally, for example comparing rates or means between locations, or measuring heterogeneity (Cochran’s Q, I²) |
| Meta-analysis | An effect estimate and its standard error from the same model at each TRE | Combined into an overall estimate using fixed or random effects, and shown in a forest plot. The overall estimate is close to, but not the same as, fitting the model on the pooled data |
| Replication | The full results of the same analysis at each TRE | Checked for whether a finding at one location holds at the others |
| Validating a model agreed in advance | Performance measures, such as discrimination (AUC) and calibration | Compared across locations, for example to see whether a published risk score performs equally well in each population. A model fitted on another TRE’s data in the same project makes this the Shared Pattern |
| Data quality and coding | Completeness, coding frequencies and data ranges | Compared to find where variables are recorded or coded differently, before results are combined |
Exact
These analyses give the same result as if the data were all in one location.
| Statistic | What each TRE sends | Why the combined result is exact |
|---|---|---|
| Min/max | Its own min/max | The min of the mins is the overall min |
| Counts | Its counts | Counts simply add up. Includes frequencies and proportions |
| Contingency tables (chi-squared, Fisher’s exact test) | Its cell counts | The tables add cell by cell, then the test runs on the summed table |
| Mean | n, Σx | Overall mean = ΣΣx / Σn |
| Variance and covariance | n, Σx, Σx², Σxy (or n, mean and sum of squared deviations) | The pooled variance is not the average of each TRE’s variance, so these totals must be sent |
| Pearson’s correlation and Fisher’s z | The same totals as covariance | Built from the exact variances and covariance |
| t-tests (one-sample, two-sample, Welch’s) | n, mean and variance for each group | Built from exact values |
| Hotelling’s T² | n, mean vector and covariance matrix | The multivariate version of the same ideas as a t-test |
| ANOVA | n, Σx and Σx² for each group | One-way is exact. Multi-way ANOVA is a linear model, so it’s exact the same way regression is |
| Linear regression (OLS) | XᵀX, Xᵀy, yᵀy, n | The coefficients, residual sum of squares and standard errors all come from these, in one round |
| Survival curves and log-rank test (Kaplan–Meier, Nelson–Aalen) | Number at risk and number of events at each event time, per group | These add across TREs at each time point, so the pooled curve and test follow exactly. All TREs must use the same time grid. If event times are grouped (e.g. by week or month) to reduce disclosure risk, the result is exact for the grouped times |
| Logistic and other generalised linear models (categorical covariates) | Event and non-event counts for each covariate combination | The tables add, and the model is fitted centrally on the summed table, giving the same fit as the pooled data. With continuous covariates, an exact fit needs the Shared Pattern, or each TRE’s results can be combined in a meta-analysis |
| Ridge regression | XᵀX, Xᵀy, n | Ridge has a closed-form solution, (XᵀX + λI)⁻¹Xᵀy, built from the same totals as linear regression |
| Linear mixed models with site-level random effects | XᵀX, Xᵀy, yᵀy, Σy, column sums of X and n | Each TRE’s totals are enough to fit the model centrally. Random effects below the site level (e.g. groups or organisations within a TRE) need the Shared Pattern |
| Principal component analysis (PCA) | n, Σx and the cross-product matrix Σxxᵀ | The pooled covariance matrix is exact, and the principal components are calculated from it centrally |
| Poisson and piecewise-exponential survival models (categorical covariates) | Event counts and person-time for each time interval and covariate combination | The tables add, and the model is fitted centrally on the summed table, giving the same fit as the pooled data |
Estimated
Some statistics cannot be rebuilt exactly from simple totals sent once by each TRE, but can be estimated closely. The combined result is an approximation of what would be obtained if the data were all in one location, and may differ slightly from it.
| Exact Statistic | Approximation | What each TRE sends | Why the combined result is an estimate |
|---|---|---|---|
| Quantiles (median, quartiles, IQR, percentiles) | t-digest | A t-digest: a compact summary of the distribution as weighted centroids | Digests merge into one approximate digest. Accuracy is highest near the extremes (e.g. 1st or 99th percentile) and lower near the median. Exact quantiles need several rounds of communication (the Shared Pattern) |
| Quantiles | Histograms | Counts in agreed bins | The binned counts add exactly, but quantiles can only be located within a bin, so precision depends on the bin width |
| Distinct counts | HyperLogLog | A HyperLogLog sketch of hashed identifiers | Sketches merge to estimate the number of distinct individuals across TREs, allowing for people present in more than one TRE. Typical error is around 1–2% |
| Cox regression | Piecewise-exponential models | Event counts and person-time for each fine time interval and covariate combination | A piecewise-exponential model with fine time intervals closely approximates the Cox model. An exact Cox model needs repeated exchanges between TREs (the Shared Pattern), or each TRE’s results can be combined in a meta-analysis |
| k-means clustering | Merged local clusters | Cluster centres and sizes from clustering run locally | The local centres are combined centrally. The result is usually close to, but not the same as, k-means on the pooled data |
When an analysis becomes Shared
What separates this pattern from the Shared Pattern is not the analysis itself, but whether anything calculated from one TRE’s data enters another TRE. In the Traditional Pattern, results flow out of each TRE to the central location and stop there; the only thing going into a TRE is the analysis code and the settings agreed in advance. The same analysis can fall in either pattern depending on how it is carried out.
| Analysis | Stays Traditional if… | Becomes Shared if… |
|---|---|---|
| Variance and standard deviation | Each TRE sends n, Σx and Σx² in one pass | The pooled mean is sent back so TREs can compute deviations from it |
| Kaplan–Meier and the time grid | The time grid is fixed in advance | The grid is derived from pooled event times and sent back |
| Histograms | The bins are agreed in advance | The bins are set from pooled data, such as pooled quantiles |
| k-means clustering | Each TRE clusters independently | Merged centres are sent back for refinement |
| Standardisation (z-scores) | Each TRE sends totals only | The pooled mean and standard deviation are sent back to standardise locally |