Shared Pattern
Analytical: Connected
Data Movement: Model Parameters
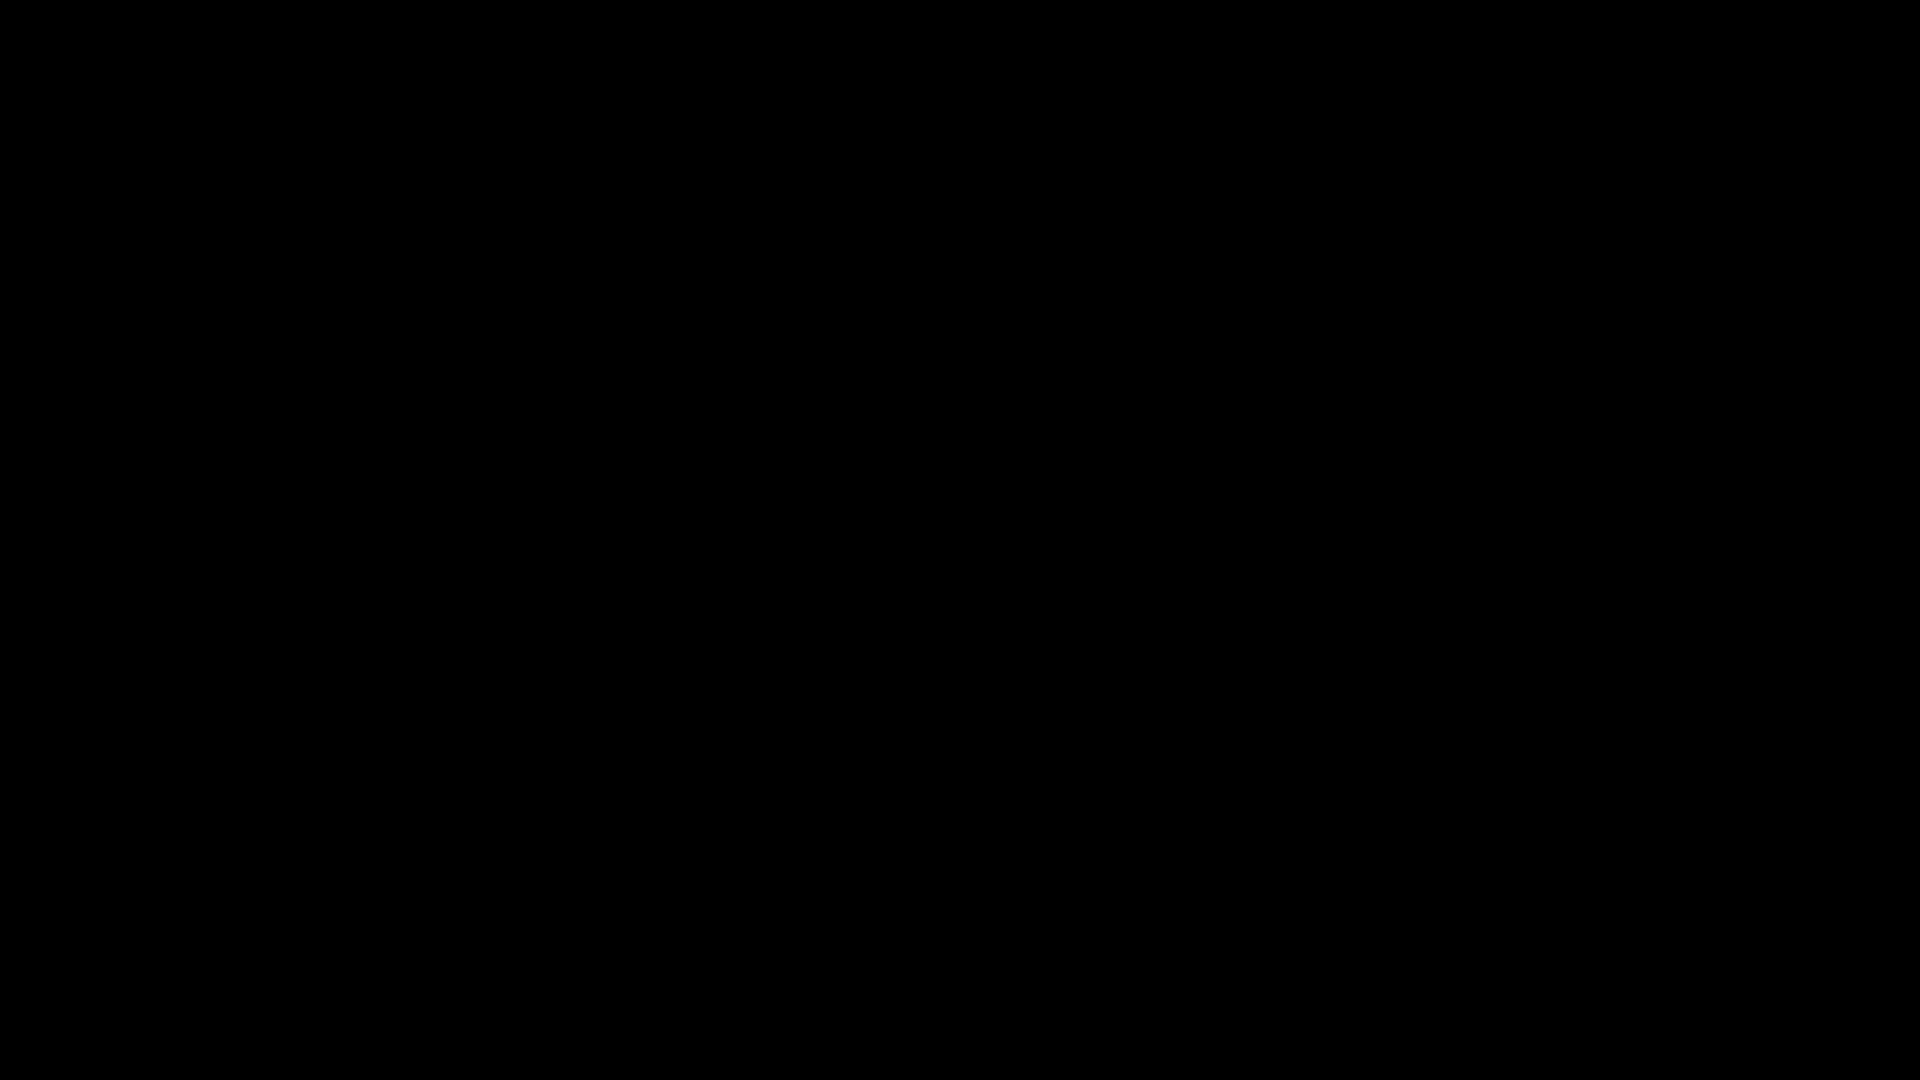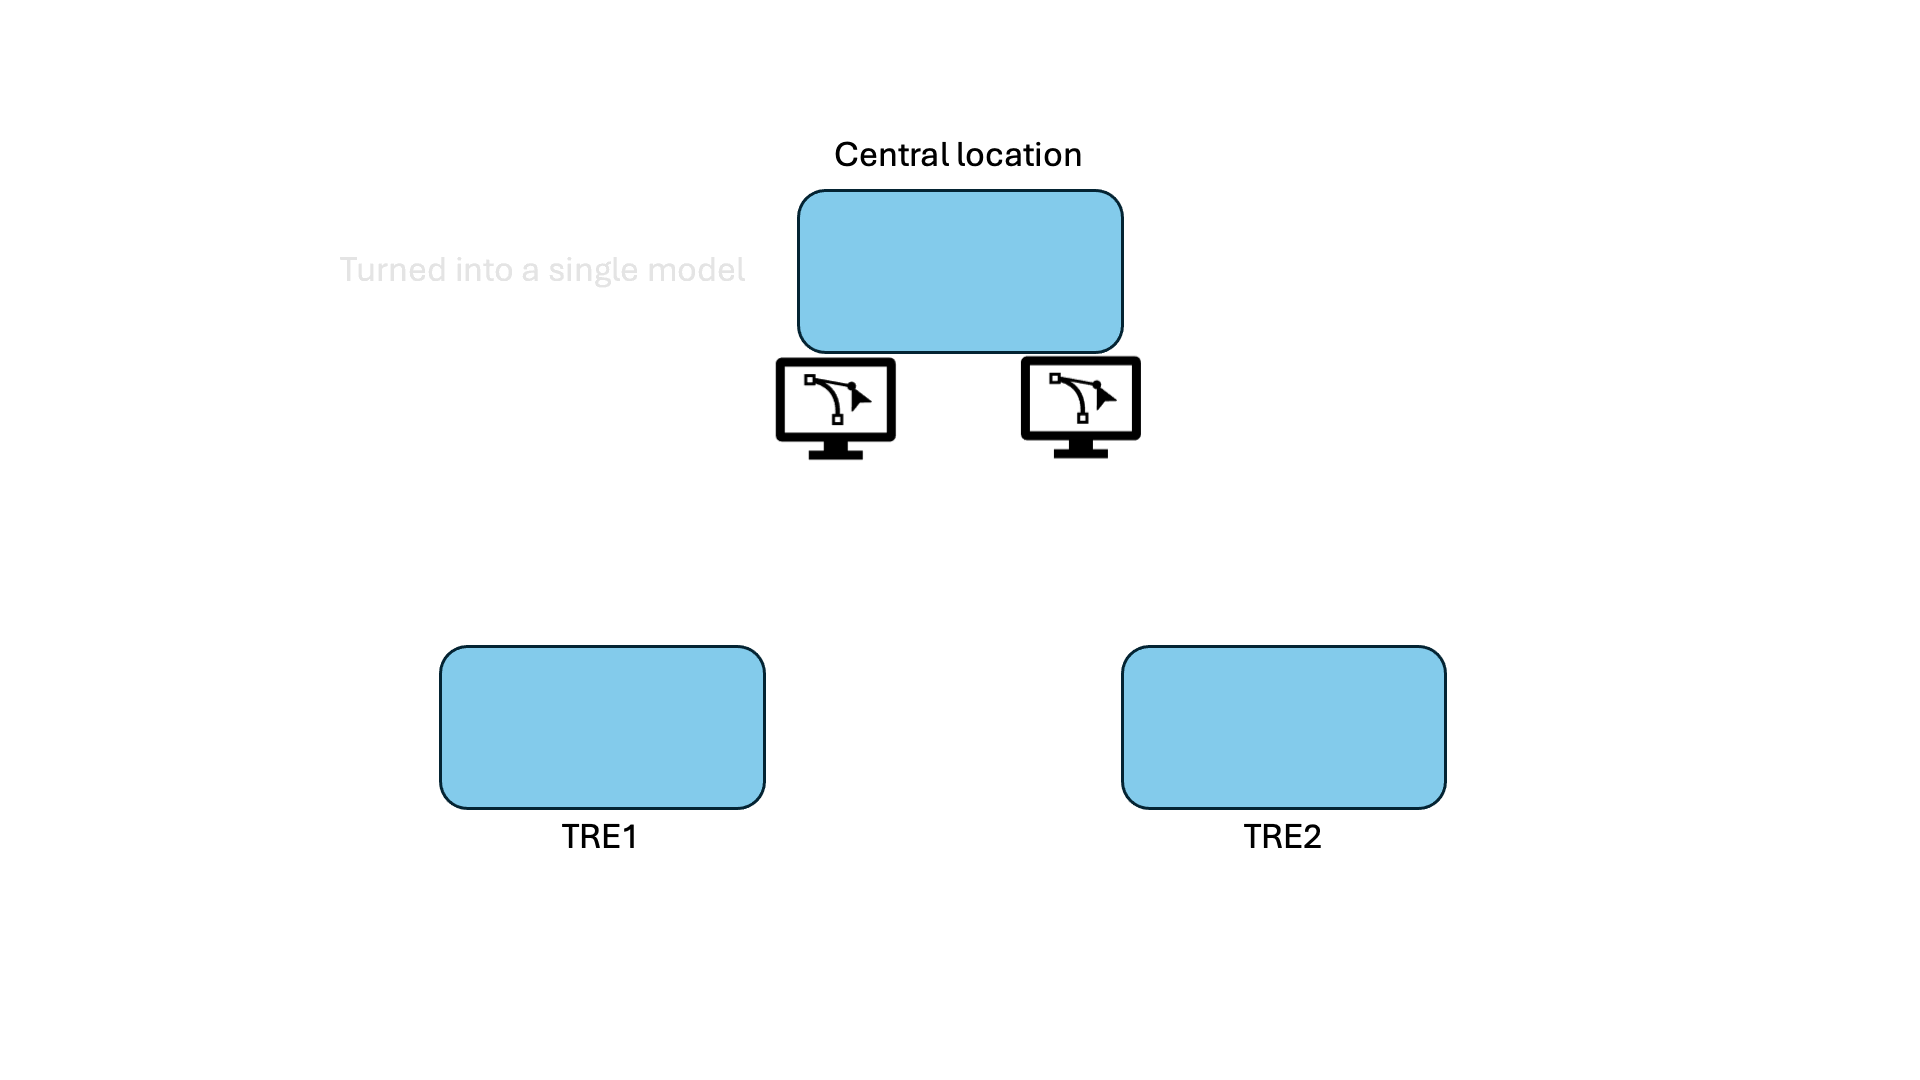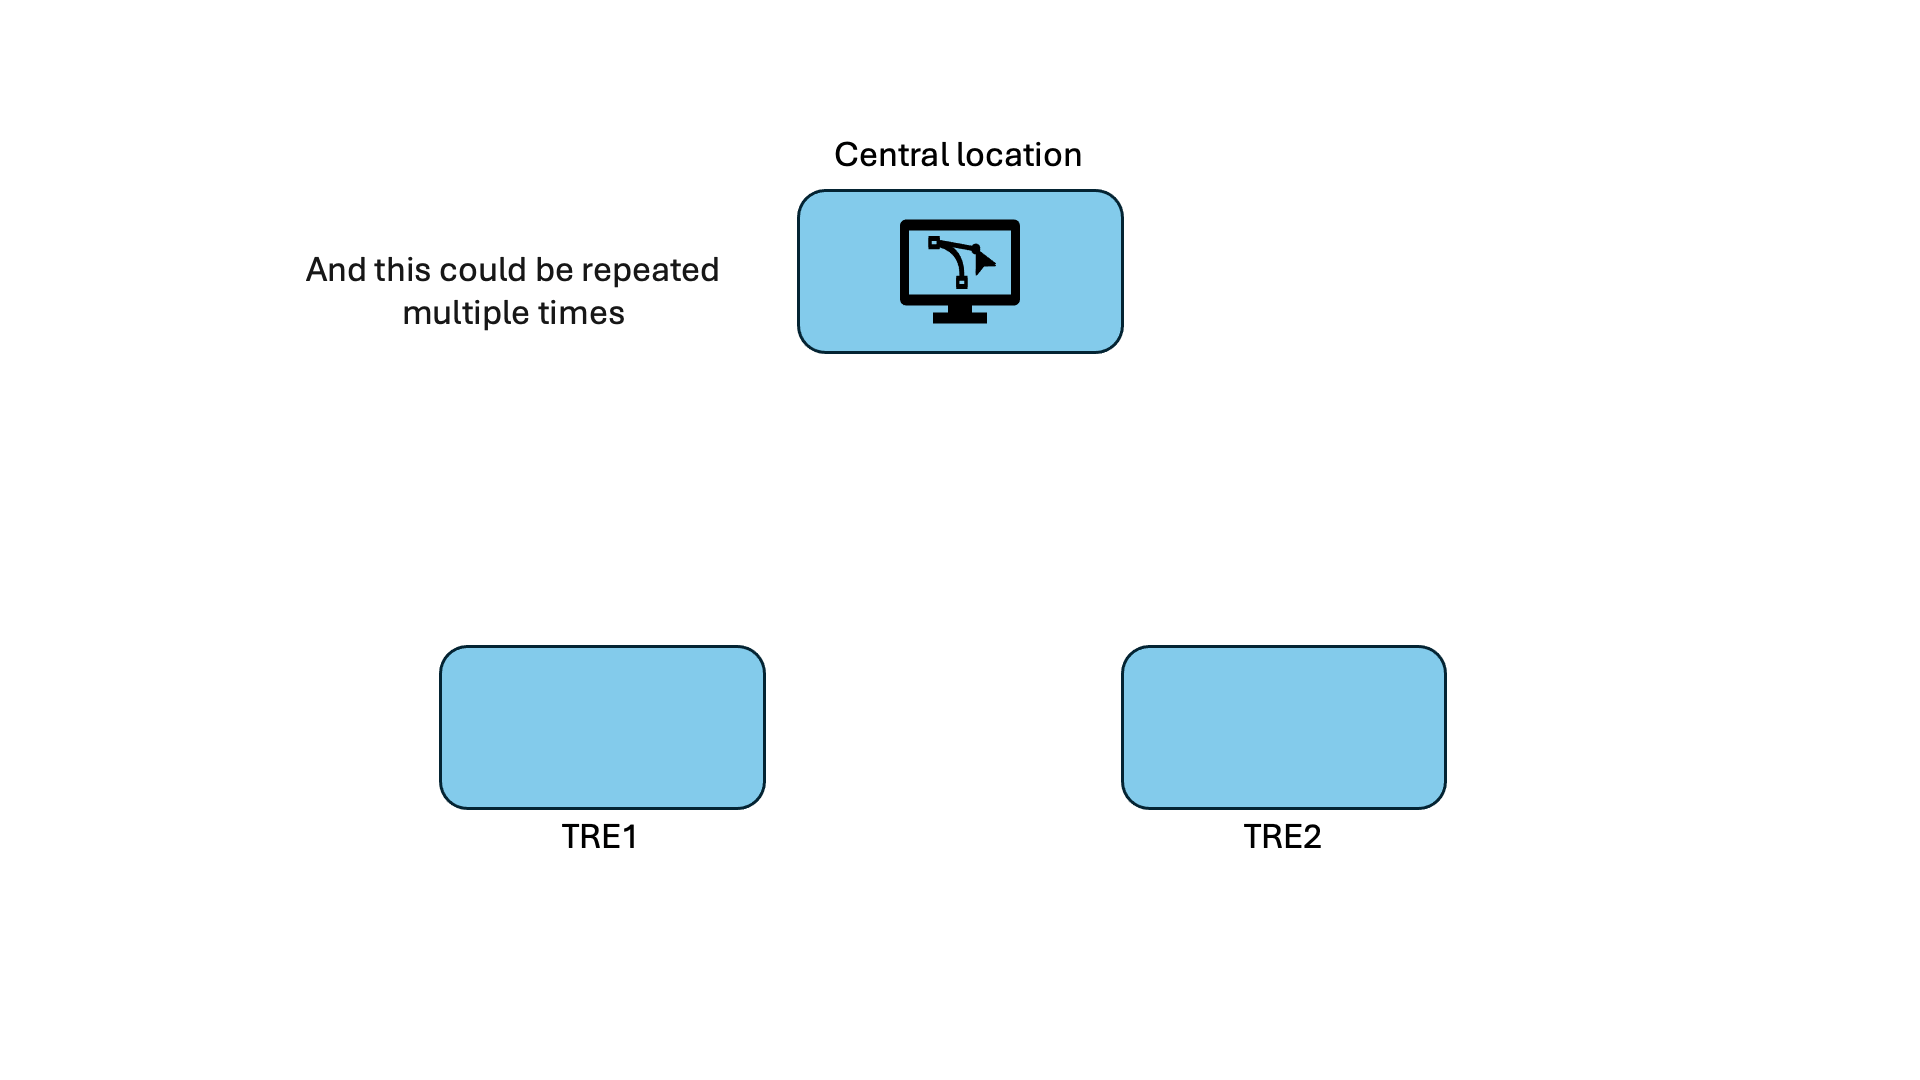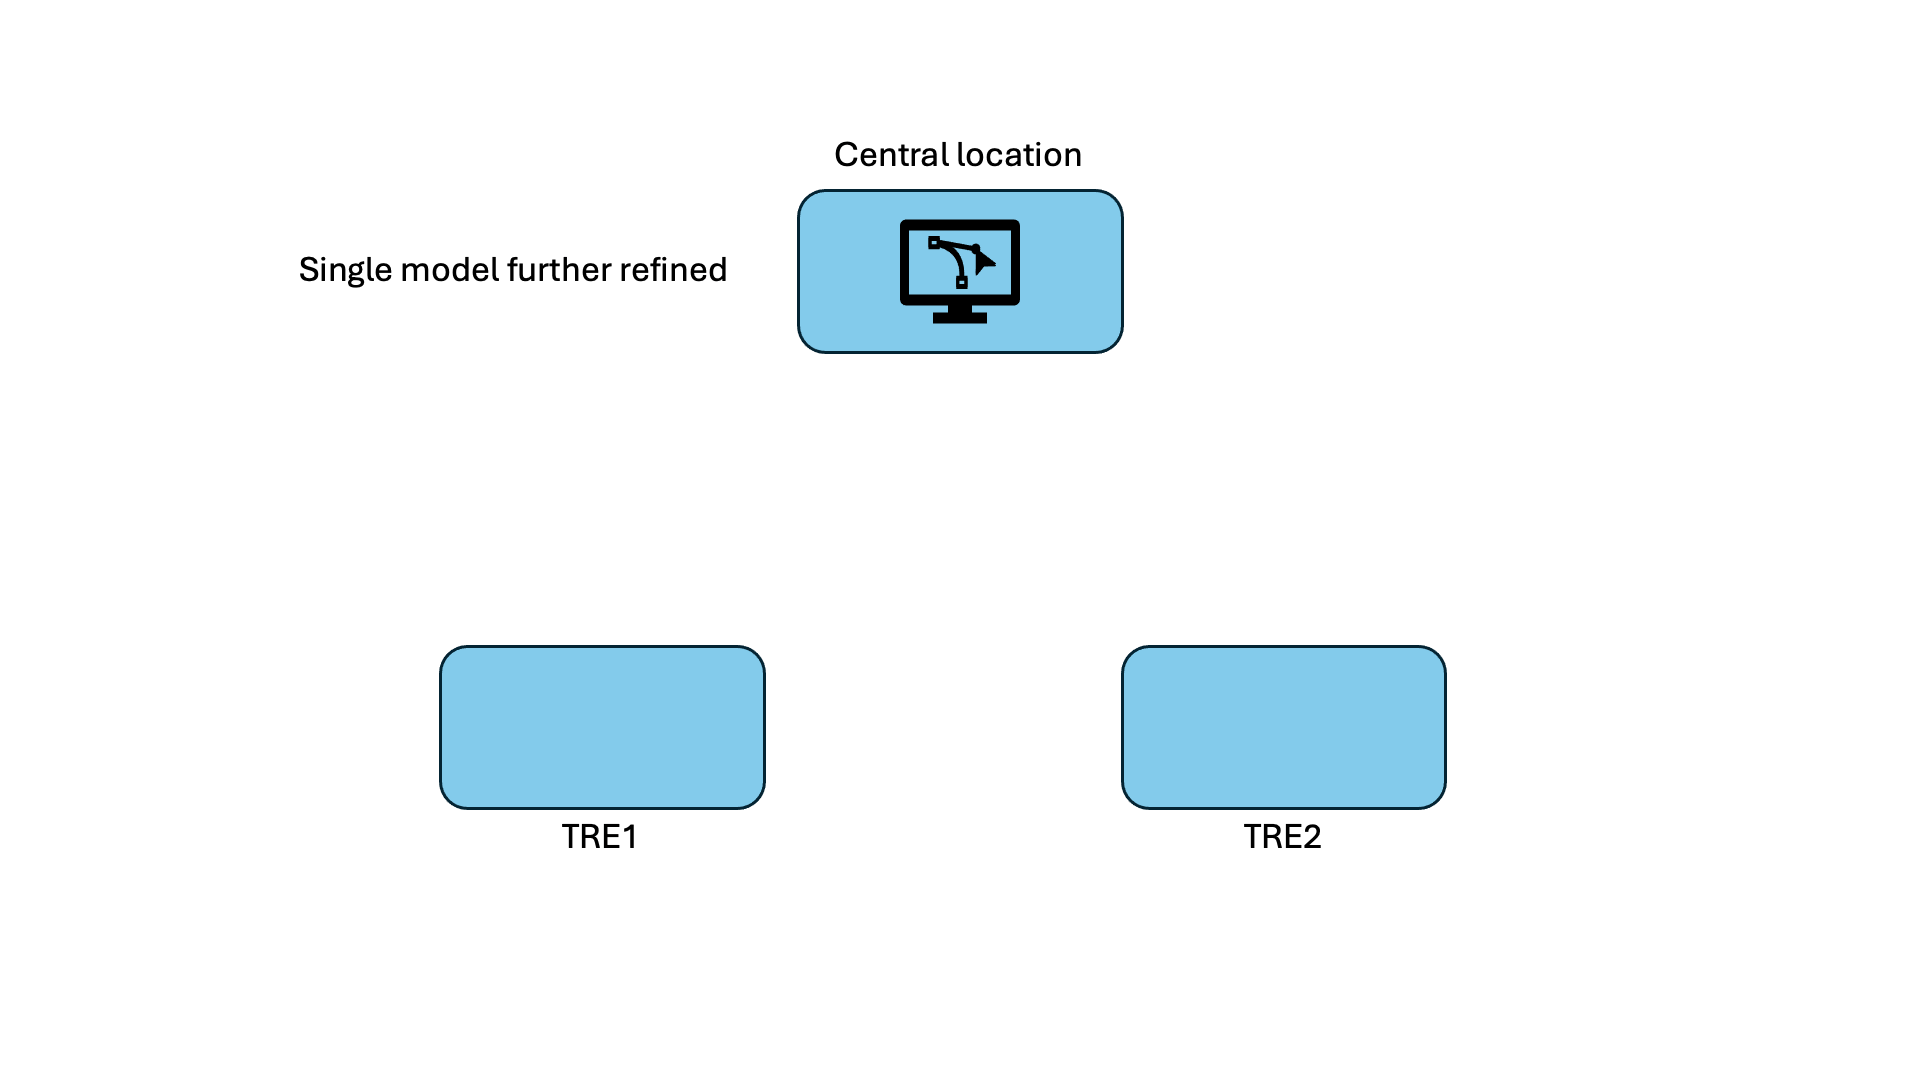
The defining feature of the Shared Pattern is that results calculated from one TRE’s data are sent into another TRE and used in its calculations. This is the case whether results are passed via a central node or directly between the TREs: when a central node combines results and sends updated parameters back, each TRE receives information derived from the other TREs’ data.
The most common method to undertake federated learning is for the model parameters to be passed via a central node, though it is also possible to share directly between TREs.
The key difference between this and the traditional pattern for a TRE is that results are combined and shared with other TREs. There is a higher level of trust required between the TREs as they must trust the sharing of some information, not only with the researcher, but also other TREs.
Trust and egress
Each exchange is both an egress from one TRE and an ingress into the others. Model parameters can carry information about the individuals they were fitted on, so a TRE receiving them is taking in derived data about another TRE’s individuals, and its governance has to accept that.
Most analyses in this pattern are iterative. A logistic regression might need 5–10 rounds, and training a neural network can take thousands. Checking every round by hand is impractical, so this pattern usually relies on the semi-automated or fully automated Egress Inspection Patterns. Comparing updates across rounds can also reveal more about individuals than any single update, which is why techniques such as differential privacy and secure aggregation are often used.
Analyses
In a typical analysis, the central location sends the current estimate to each TRE, each TRE returns an update calculated on its own data, and the cycle repeats until the estimate stops changing. These tables are not comprehensive, and only encompass some common analyses that can be achieved by the shared pattern.
Exact
These analyses converge to the same result as if the data were all in one location.
| Analysis | What each TRE sends each round | Why the combined result is exact |
|---|---|---|
| Logistic, Poisson and other generalised linear models (any covariates) | Score vector and information matrix at the current coefficients | These add across TREs to give the pooled Newton–Raphson step, so the model converges to the pooled fit |
| Generalised estimating equations (GEE) | Estimating equation contributions and their derivatives at the current estimates | The equations add across TREs, provided each cluster sits within one TRE |
| Cox regression, stratified by site | Score and information from its own risk sets at the current coefficients | The stratified partial likelihood is a sum over sites, so the summed updates converge to the pooled stratified fit |
| Parametric survival models (Weibull, accelerated failure time) | Score and information at the current parameters | The log-likelihood is a sum across TREs |
| Linear mixed models with random effects below the site level (e.g. groups or organisations within a TRE) | Likelihood contributions at the current parameters | The likelihood is a sum across TREs, provided each cluster sits within one TRE |
| Exact quantiles (e.g median) | Count of values below the current candidate value | Bisection narrows the candidate until it lands on the exact pooled value |
| Lasso and elastic net regression | Gradient contributions, or local solutions under ADMM (an algorithm for splitting a model fit across sites) | Converges to the pooled penalised fit |
| k-means clustering | Per-cluster sums and counts for the current centres | Each round reproduces a pooled k-means step, so the result matches pooled k-means given the same starting centres |
| Gaussian mixture models (EM algorithm) | Per-component weighted sums and counts | Each EM step adds across TREs, so the result matches the pooled fit given the same starting values |
| Standardisation (z-scores) | One round sharing mean and variance to pool, one round to send results after standardisation | Mean, variance, and standardised results can be calculated exactly |
Estimated
These analyses give results close to, but not the same as, those from the data in one location.
| Analysis | What each TRE sends each round | Why the combined result is an estimate |
|---|---|---|
| Neural networks via federated averaging (FedAvg) | Model weights after several steps of local training | Averaging locally trained models differs from training on the pooled data, especially when the TREs’ data differ |
| Gradient-boosted trees (e.g. federated XGBoost) | Binned gradient totals for candidate splits | Splits are chosen from bins built from merged summaries, so they can differ slightly from those found on pooled data |
| Random forests | Locally built trees, or binned split summaries | The combined forest approximates one trained on pooled data |
| Any model trained with differential privacy | Updates with added random noise | The noise protects individuals but moves the result away from the pooled fit |
Overlap with the Traditional Pattern
Several of these analyses can also be carried out in the Traditional Pattern, where nothing is sent back into a TRE. The trade-off is fewer exchanges and simpler egress in the Traditional Pattern, against exact results for a wider range of models in the Shared Pattern.
| Analysis | In the Traditional Pattern | What the Shared Pattern adds |
|---|---|---|
| Generalised linear models | Exact with categorical covariates only, otherwise each TRE’s results are combined in a meta-analysis | An exact fit with continuous covariates |
| Cox regression | Estimated via piecewise-exponential models, or by combining each TRE’s results in a meta-analysis | An exact fit when stratified by site |
| Quantiles and median | Estimated via t-digest or histograms | Exact values |
| Mixed models | Exact with site-level random effects | Random effects below the site level |
| k-means clustering | Estimated by merging local clusters | An exact match to pooled k-means |
An analysis that looks like it belongs in the Traditional Pattern also becomes Shared if a pooled value is sent back into the TREs, for example a pooled mean used to standardise data locally. See When an analysis becomes Shared.